Back to portfolio
AI Research · University of Toronto · Deep Learning: Theory and Data Science · 2026
Truncated Transformer Reasoning
Can inference-time sampling recover the reasoning a model loses when its later layers are removed?
Overview
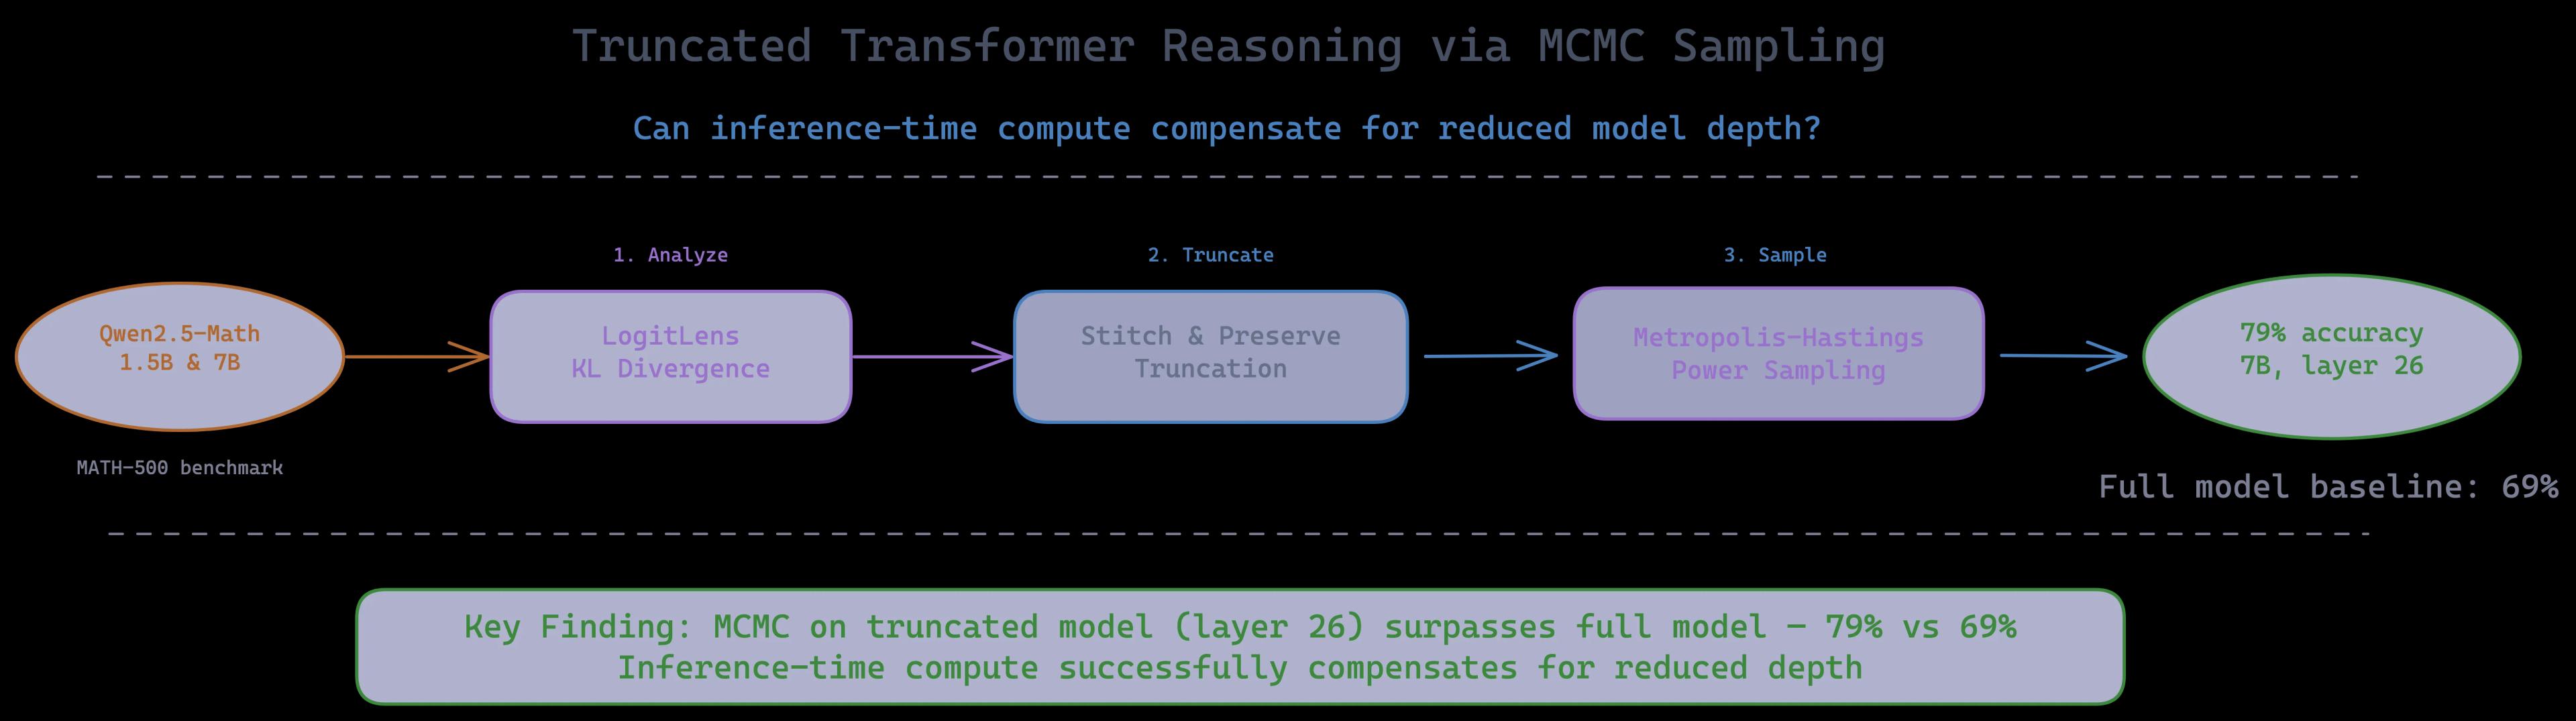
Later transformer layers often change the output distribution very little, and recent work suggests reasoning traces already exist in base models. This project asks whether extra compute at inference time can make up for reduced depth. It truncates Qwen2.5-Math models (1.5B and 7B) and runs power sampling on the truncated models, evaluated on MATH500.
What I built
- Wrote the LogitLens analysis: the KL divergence between each layer's prediction and the final output, to find where representations saturate.
- Ran power-sampling and standard-generation experiments on models truncated to layers 0 to k plus the original final layer and norm.
- Set up the cluster environment and Slurm jobs for the experiment sweep.
Tech stack
PythonPyTorchHugging Face TransformersSlurm